Ask a bank for its exposure to a single counterparty and the answer depends on who you ask. Credit risk counts committed lines. Finance counts drawn balances at book value. Treasury nets collateral. Regulatory reporting applies the definition in the template due that month. Each number is correct within its mandate, and the reconciliation between them is done by people, late, in a spreadsheet. The same is true of customer, default, liquidity, adjusted EBITDA and assets under management. This paper is about why that is still so a decade after supervisors demanded it be fixed, and why the cost changed in 2026.
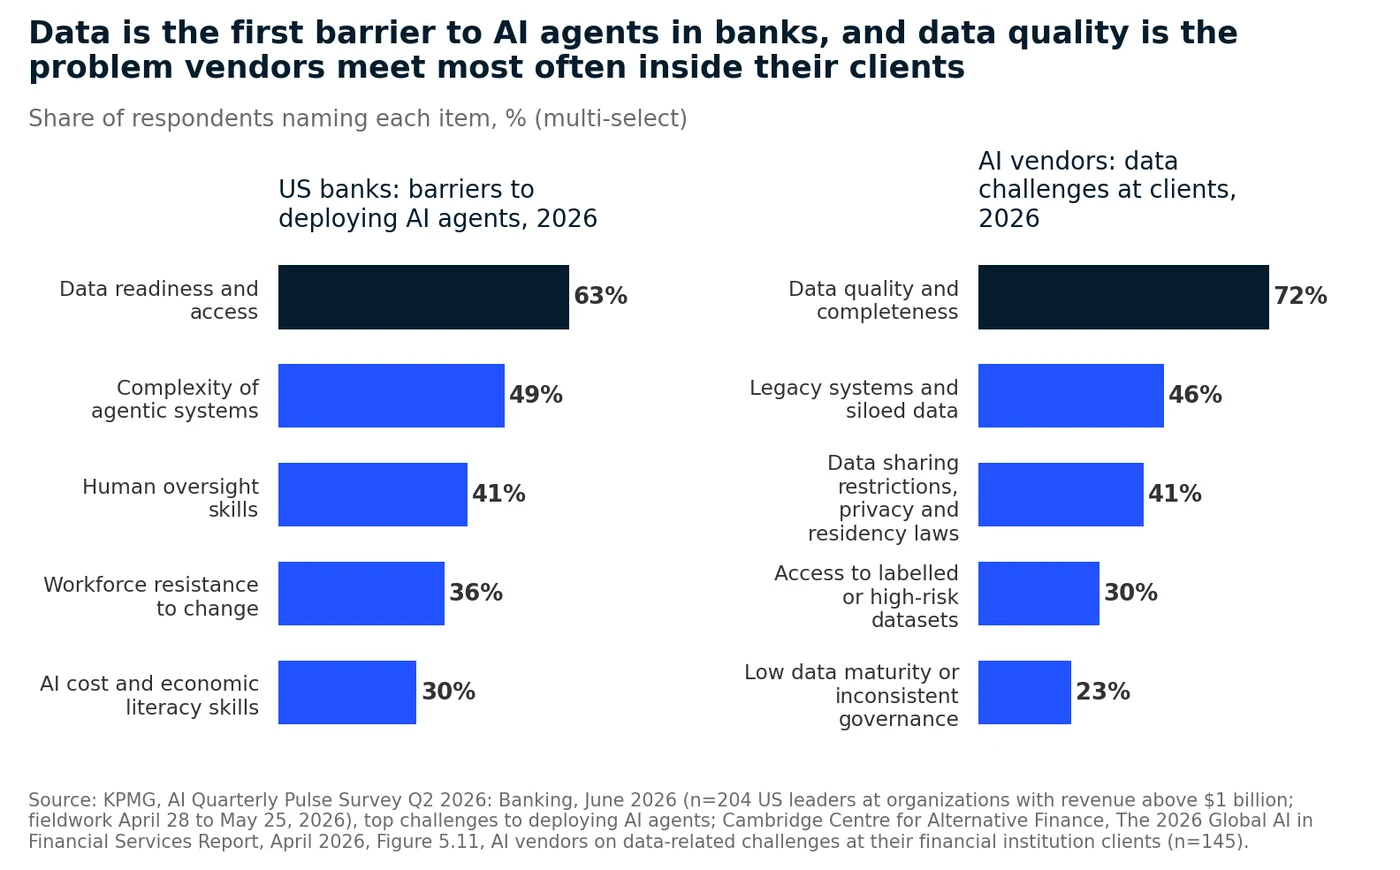
The 2026 evidence puts data, not models, at the front of every queue. In KPMG's second-quarter pulse of 204 US banking leaders, data readiness and access was the most cited barrier to deploying AI agents, at 63 percent, ahead of the complexity of the agents themselves at 49 percent.1 In the Cambridge Centre for Alternative Finance's global survey of 628 institutions, vendors and regulators, data availability and quality was the leading pain point for 66 percent of AI vendors, 46 percent of regulators and 40 percent of industry, and 72 percent of the 145 vendors surveyed named data quality and completeness as the problem they meet most often inside their financial institution clients, ahead of legacy and siloed systems at 46 percent (Exhibit 1).2 In September the Chair of the ECB's Supervisory Board, Claudia Buch, described the same thing from the inside: more than 90 percent of directly supervised banks integrate AI into their operations and 85 percent use generative AI, yet "new technologies cannot compensate for poor underlying data or fragmented legacy systems," and "risk data aggregation remains an area where progress is often too slow."3
Exhibit 1
Our argument is that the obstacle those surveys call data quality is, for the most part, a definitions problem. The records are usually there. What is missing is an authoritative statement of what each number means, which function owns that meaning, when it took effect, and which version applies to which use. Until 2026 that gap was absorbed by experienced people who knew which number to trust. Language models do not know. They answer confidently with whichever definition they find first, and the 2026 benchmarks show how often that is the wrong one. The same benchmarks show that governed definitions, with ownership and policy attached, move accuracy more than the choice of model, which makes them the highest-return investment a chief data officer or chief risk officer can make for AI this year.
The same word, five correct meanings
Every financial concept that matters has several defensible definitions, and the differences are not errors. Exposure can be gross, net of collateral, drawn, committed, or at default. A customer can be a legal entity, a group, a relationship or an account holder, and the count changes with each. Default is 90 days past due in the regulatory book, unlikeliness to pay in the credit book, and a distressed exchange in the rating agency's. Adjusted EBITDA is whatever the credit agreement says it is. In every case the institution has, somewhere, a document that defines each version. Almost nowhere does it have a single governed record that says which version applies, who may change it, and from what date.
Supervisors see the consequences in the reconciliations. In its September 30 letter to the CFOs of UK deposit-takers on IFRS 9 expected credit losses, the PRA defined post-model adjustments as "all model overlays, management overlays, model overrides, or any other adjustments made to model output," then reported that "the maturity, documentation and consistency of application of firms' frameworks varied across firms and portfolios," that accountability for data was sometimes fragmented across systems, teams and locations, and that "a common observation was the use of manual reconciliations, trend analysis and other downstream reviews," which give less assurance over data quality at source.4 In February the PRA's discussion paper on the future of banking data counted a collection that "spans over 400 templates," with capital covered in around 120 of them and credit risk in more than 100, asked firms whether "divergence of regulatory and internal definitions, lack of central dictionary" drives their costs, and concluded that "standardising definitions across multiple data collections presents a clear direction for reducing costs."5 The EBA counted 92,000 data points in roughly 220 templates in April.6
The US agencies arrived at the same object from the model side. SR 26-2, which replaced the 2011 model risk guidance in April, says that aggregate model risk includes "reliance on common assumptions, data, or methodologies," and that validation of conceptual soundness must cover "key modeling choices, assumptions, qualitative judgments, and data selection."7 A definition that two models apply differently is exactly that kind of common assumption. Inside data teams the ownership gap is measured every year: in dbt Labs' 2026 survey of 363 practitioners and leaders, 41 percent named ambiguous data ownership as a persistent obstacle, unchanged from the year before, while 71 percent were concerned about incorrect data reaching stakeholders.8
A decade of BCBS 239 has not fixed it
The Basel Committee's principles for risk data aggregation were issued in 2013 with a 2016 compliance date for global systemically important banks. The 2026 record is candid about where that ended up. The Committee's January newsletter said that "implementation has evolved over the years," that "meeting the intended outcomes of the Principles remains a continuous effort," that "a data-driven culture within some organisations remains a work in progress," and that the obstacles are resistance to change, fragmented responsibilities and limited senior management attention. Lineage remains "a challenging component of BCBS 239 for banks," and the use of AI for aggregation "is still in the early stages."9 The last granular assessment, in 2023, found 2 of 31 G-SIBs fully compliant, and their average compliance score had improved by 0.03 on a four-point scale between 2019 and 2022.10
The ECB's numbers are the most specific. In its aggregated results of the 2025 supervisory review, new qualitative measures on internal governance concentrated in three areas: the management body at 23 percent, risk data aggregation and risk reporting at 20 percent, and the risk management framework at 20 percent, with every other governance area at 4 to 9 percent. Progress on risk data was "slow and insufficient," difficulties with "data accuracy, integrity, completeness, timeliness and adaptability are still widely encountered," and the supervisory priorities for 2026 to 2028 record "no improvement in the relevant average sub-score as compared with last year" (Exhibit 2).11 In January, Supervisory Board member Sharon Donnery and the ECB's head of supervisory strategy wrote that supervisors "will also closely monitor follow-up actions to address deficiencies in risk data aggregation and risk reporting, given the slow pace of progress so far," and the priorities say that where deviations persist the ECB may use binding measures and its enforcement and sanction powers.12
Exhibit 2
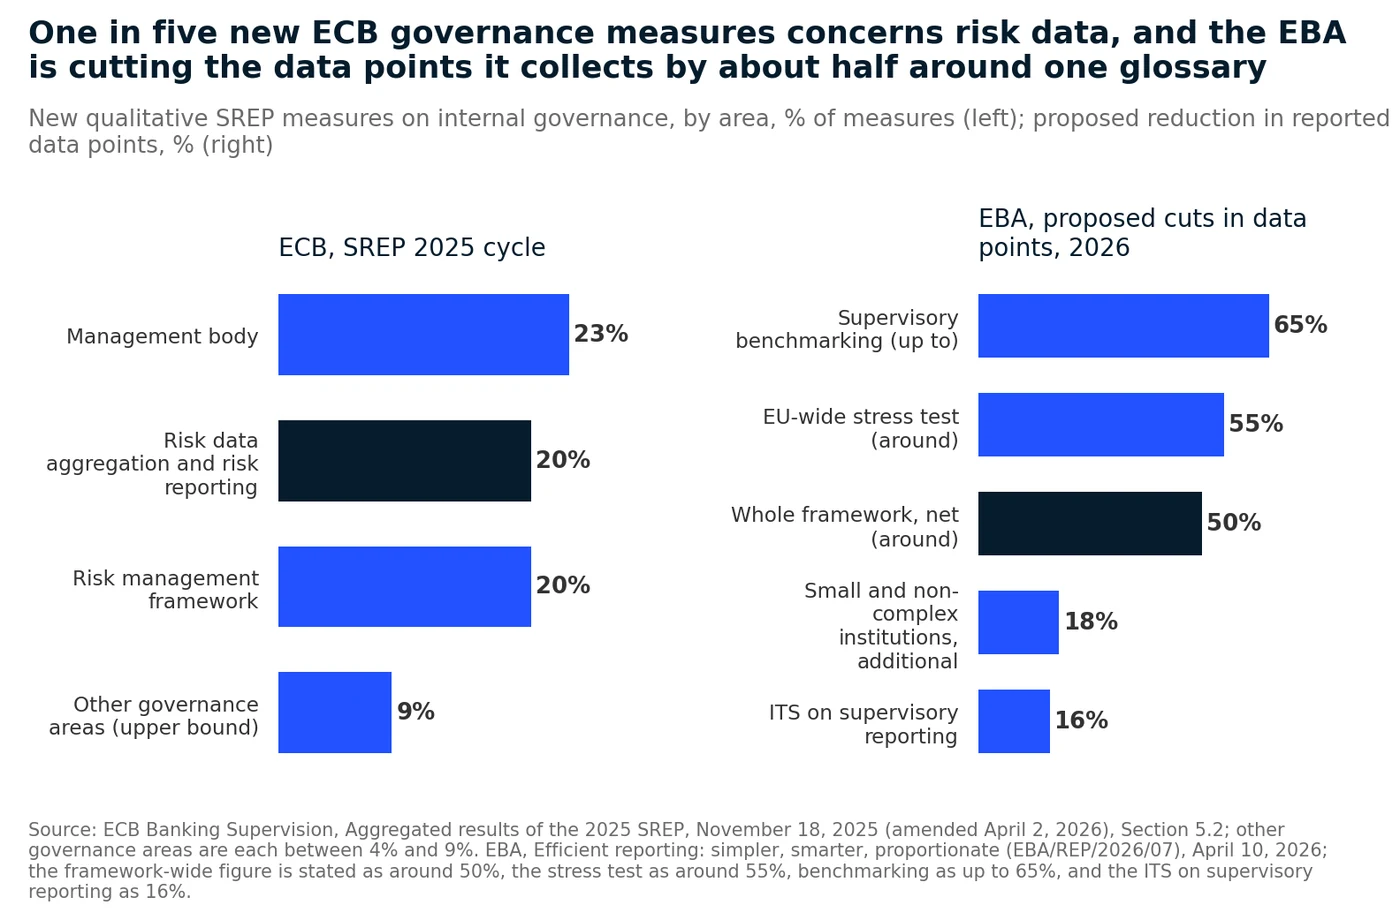
Why did a decade of effort, backed by inspections and the threat of capital add-ons, not close the gap? Our reading is that most programs treated BCBS 239 as an infrastructure and lineage exercise and left the definitions where they were. A bank can build a warehouse, a lineage graph and a data quality dashboard and still have five exposures, because the warehouse faithfully stores all five. Definitions were catalogued rather than governed: recorded in a glossary nobody is accountable for, without an effective date, and without any mechanism that forces a system to use the right one. That is why the sub-score does not move. The regulators are now simplifying their own side, and the direction is identical: the EBA proposes to cut reported data points by around 50 percent across its framework and 55 percent in the stress test, around a harmonized glossary and a common European data dictionary planned for 2026, and the PRA's first principle for its future collection is to collect data "once and well."5,6 Institutions that cannot say what their own numbers mean will find it hard to supply a supervisor who now can.
In 2026 the cost became visible
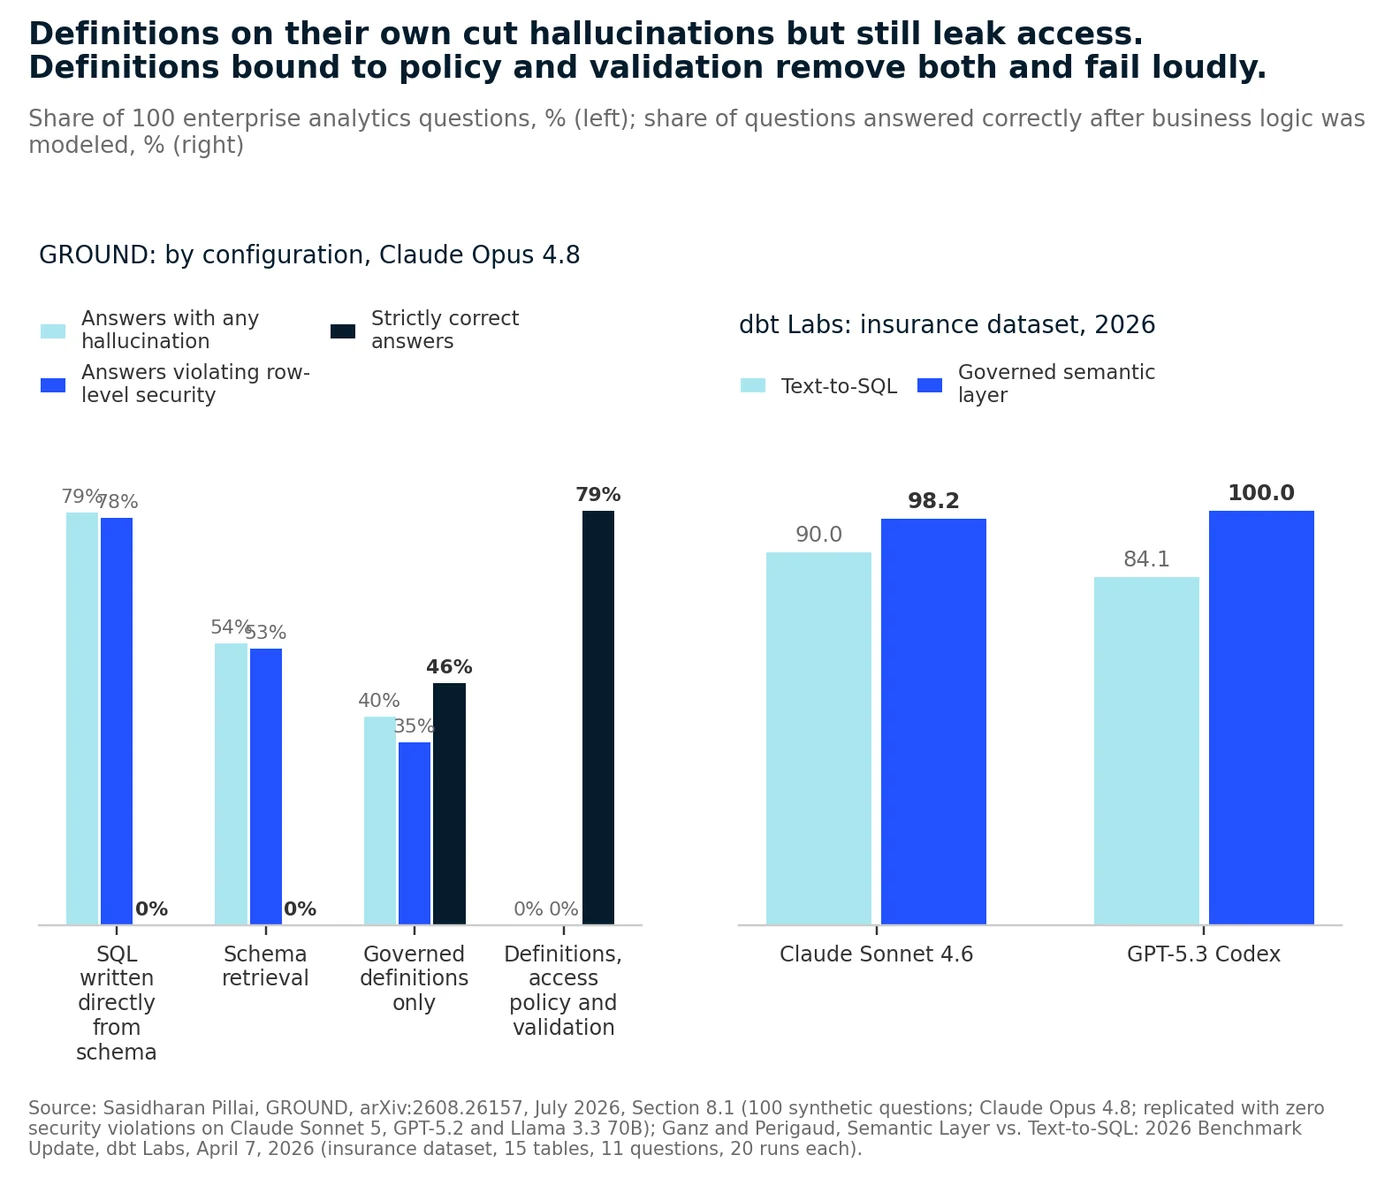
For as long as the people who built the reports were the people reading them, the cost of multiple definitions was a quiet tax: reconciliation hours, late board packs, the occasional restatement. Language models changed the accounting. They retrieve the definition that is nearest, not the one that is authoritative, and present the result with the same confidence either way. The Stanford AI Index, published in April, reports that on a 6,000-question knowledge benchmark hallucination rates across 26 leading models range from 22 to 94 percent, that even the best summarization models introduce unsupported claims 1.8 to 5.4 percent of the time, and that documented AI incidents rose to a record 362 in 2025 from 233 the year before.13 dbt Labs' April benchmark put the failure mode in one sentence: "With text-to-SQL, failure looks like a plausible but incorrect answer. With the Semantic Layer, failure looks like an error message."14
The enterprise benchmarks of 2026 quantify how often the plausible answer is wrong. In GROUND, a 100-question enterprise analytics benchmark run on Claude Opus 4.8, a model writing SQL directly from the schema produced at least one hallucination in 79 percent of answers and violated row-level access controls in 78 percent; schema retrieval reduced those figures only to 54 and 53 percent.15 In EnterpriseRAG, 13 frontier models satisfied individual instructions about 80 percent of the time but met all of a task's requirements in only 26.8 percent of responses, with the deepest failures under "knowledge gaps and factual conflicts," which is what a second definition of the same term looks like to a retrieval system.16 On the Finance Agent Benchmark, updated on October 7 with Gemini 4 Argon at the top of 76 models at 65.4 percent, the best scores on tasks that depend on house definitions remain low: adjustments 60.5 percent, comparables 52.0, precedents 49.8, financial modeling 34.5, and no model passes every part of a question more than 51 percent of the time.17 BigFinanceBench's authors set the standard an auditable financial answer must meet: it has to show "which source was chosen, which period and accounting definition were used."18 No model can satisfy that for an institution that has not written its definitions down.
Two further costs are systemic. Christine Lagarde told the ESRB conference on October 1 that nearly nine out of ten significant euro area banks use generative AI, that the frontier models are "few in number," and that the ESRB's scientific committee warns "the widespread use of similar models may lead firms to assess a shock in much the same way"; her proposed remedy was that firms train their agents on proprietary data, which presupposes that the proprietary data means something consistent.19 And in February, ECB Supervisory Board member Pedro Machado said that "AI shifts supervisory attention upstream from models to data," named "fragmented ownership, with responsibility split across IT, data science teams, business lines and control functions" as the concern supervisors keep meeting, and said a bank that cannot explain a model's output in decision-relevant terms "cannot truly control that model."20 Explaining an output requires the definition it applied. In 2026 that is the difference between an answer that can go into a board pack and one that cannot.
What governed definitions do to accuracy
The evidence that definitions, rather than models, are the binding constraint now comes from four independent 2026 studies on current models, and the direction is the same in every one. EntSQL, a benchmark of 1,066 enterprise questions across five business domains whose answers depend on private metrics and reporting conventions, tested eight frontier models three ways: with the schema alone, with the schema plus the long business documents in which the definitions are buried, and with the exact definition supplied. Every model improved at every step, and none did well without the definition. Claude Code on Sonnet 4.6 went from 6.8 percent with the schema to 15.9 with the documents and 21.4 with the definition; GPT-5.4 from 4.8 to 11.2 to 16.7; GLM 5.1 from 5.5 to 12.9 to 17.1 (Exhibit 3).21 A document that contains the definition somewhere is worth roughly half as much as the definition itself, and the spread between the best and worst model in any column is smaller than the gain from moving one column to the right.
Exhibit 3
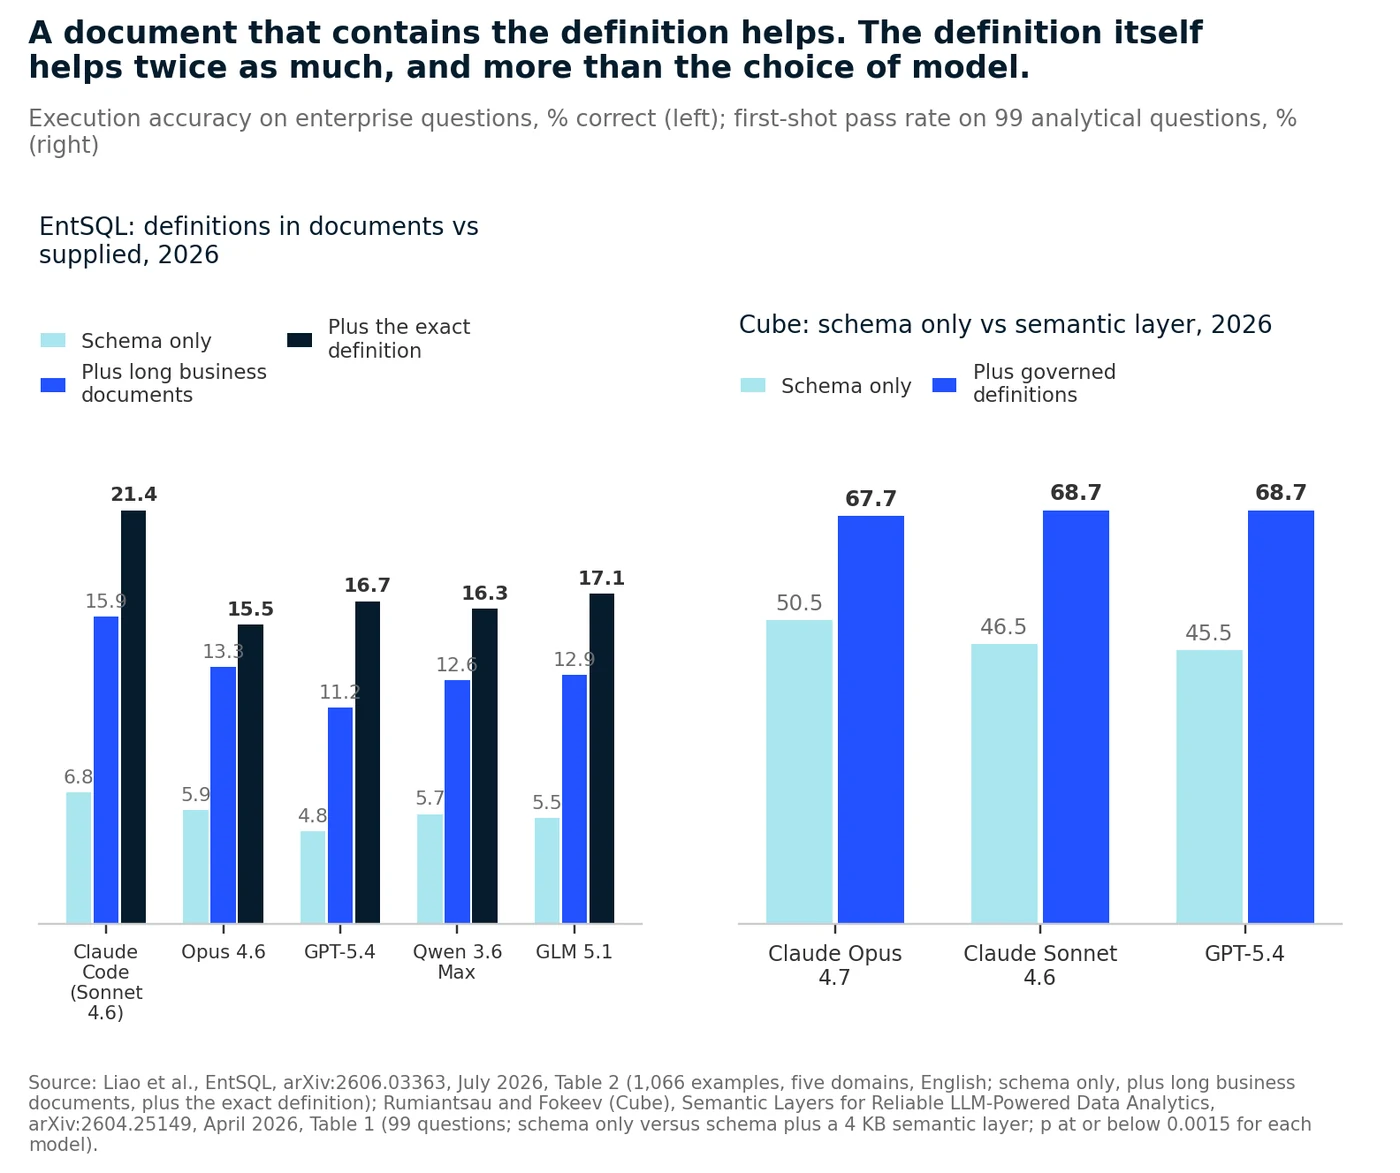
Cube's April paired study made the same point with a different design. Three frontier models answered 99 analytical questions twice, once with the schema and once with a four-kilobyte document of measures, conventions and disambiguation rules. Claude Opus 4.7 rose from 50.5 to 67.7 percent, Claude Sonnet 4.6 from 46.5 to 68.7, and GPT-5.4 from 45.5 to 68.7; every improvement was significant at p at or below 0.0015, and the three models were statistically indistinguishable in both conditions.22 dbt Labs found on a 15-table insurance dataset that once the business logic was modeled, a governed semantic layer answered 98.2 and 100 percent of questions with Claude Sonnet 4.6 and GPT-5.3 Codex, against 90.0 and 84.1 percent for direct text-to-SQL with the same models, and that where the governed layer failed, it declined to answer rather than returning a number.14
GROUND separates the definition from its governance, and that separation is the finding this paper rests on. Supplying exact metric definitions without access policy cut the hallucination rate from 79 to 40 percent and lifted strict accuracy from zero to 46.3 percent, but the model still leaked data across tenant boundaries on 35 percent of questions. Only when the definitions were bound to join paths, grain, filters, row-level security and validation before execution did hallucinations fall to zero and strict accuracy reach 79.3 percent, a result replicated with zero security violations on Claude Sonnet 5, GPT-5.2 and Llama 3.3 70B (Exhibit 4).15 Three caveats apply: two of the four studies are vendor-authored, all use question sets in the hundreds, and none is a bank. But they agree with one another, with the Finance Agent Benchmark's category scores, and with Gartner's May statement that "context with semantic coherence will become a cost-control and trust strategy, not a nice-to-have."25 A glossary is not enough. A definition has to carry its owner, its scope, its effective date and the policy on who may see what it computes.
Exhibit 4
Supervisors are converging on ownership and effective dates
None of the 2026 supervisory texts uses the phrase governed definitions, but each describes a piece of the object. The Financial Stability Board's June consultation, with the final report due this month, makes data governance its seventh sound practice: institutions "establish appropriate data governance to maintain data that is fit-for purpose for training, testing, and using AI (i.e. accurate, complete, consistent, reliable, secure)," with "clear accountability in different scenarios," procedures "for the classification and labelling of data, including metadata," and documented lineage.23 The Monetary Authority of Singapore's guidelines, issued on October 7 and binding from October 2027, require institutions to "maintain inventories at an appropriate level of granularity, assess the risk materiality of AI use cases, and apply proportionate controls across the AI life cycle," with data governance named first among those controls.24 SR 26-2 makes data selection and qualitative judgment part of conceptual soundness while placing generative and agentic AI outside its scope, so the definitions those systems apply are, for now, validated by nobody.7
The gap between what is deployed and what is governed is widening. Evident's October index of 50 large banks found the average AI score up 26 percent in a year, yet only 12 percent of use cases report impact against an operational KPI and barely 1 percent disclose a financial return.26 KPMG's third-quarter pulse found multi-agent deployments quadrupling from 6 to 25 percent of organizations in a single quarter, with data readiness still the top barrier.27 McKinsey's August survey of 1,719 organizations showed 44 percent scaling AI enterprise-wide while the share reporting any EBIT effect stayed at 37 percent for a second year.28 An institution that scales agents across functions that define exposure five ways will produce five confident answers at machine speed. The supervisory texts, read together, ask for the one object that prevents it: a record of what each number means, owned by a named function, with the date it took effect and the policy that governs its use.
What the people shaping the next four years expect
The forecasts worth weighting come from people with a supervisory mandate, a balance sheet or a research franchise at stake, and in 2026 they were specific about data.
- Semantics becomes infrastructure. Gartner predicted on March 11 that by 2030 universal semantic layers will be treated as critical infrastructure alongside data platforms and cybersecurity, that half of organizations will use autonomous agents to turn governance policies into machine-verifiable data contracts, and that half of agent deployment failures will stem from insufficient runtime enforcement.29 In May it added that organizations prioritizing semantics in AI-ready data could raise agentic accuracy by up to 80 percent and cut costs by up to 60 percent by 2027, and that regulators will demand "greater semantic transparency."25
- Supervisors will escalate on risk data. Claudia Buch said in September that accountability for AI decisions "cannot be outsourced to a model or to a third-party provider" and that strong risk data aggregation capabilities "determine how effectively banks can exploit AI and advanced analytics."3 The ECB's 2026 to 2028 priorities commit to targeted inspections and, where deviations persist, binding measures.11 The FSB's final sound practices arrive this month, and MAS's guidelines bind from October 2027 with agentic AI guidance to be consulted on in 2027.23,24
- The obstacle is organizational, and leaders know it. In the Bean and Davenport survey of senior data and AI executives at nearly 110 large companies, 42.7 percent of them in financial services, 39.1 percent now have AI in production at scale, up from 4.7 percent in 2024; 93.2 percent say culture and change management, not technology, are the greatest impediment; 90 percent have appointed a chief data or data and AI officer, and only 25.8 percent of those officers have held the role for more than five years.30 In Workiva's survey of 1,497 finance and reporting professionals, 96 percent said the CFO, CIO and chief security officer must unite around a shared data governance strategy.31
- Model homogeneity raises the value of proprietary meaning. Lagarde's October warning that similar models will assess shocks the same way, and her remedy of agents trained on proprietary data, make an institution's own definitions a source of diversification as well as accuracy.19
Our own expectation, grounded in those views and in the benchmarks above, is that between now and 2030 the definitions layer will move from a data-office project to a line item that risk committees and supervisors examine directly. By 2028 we expect the first supervisory findings that turn not on a model but on an institution's inability to state which definition of exposure, default or liquidity an AI system applied and who owned it on the day it was applied. By 2030 we expect governed definitions with owners and effective dates to be a standing condition for deploying agents in any function that reports to a regulator, and the institutions that built them early to be the ones whose EBIT figures finally move. The models will keep converging; EntSQL and Cube already show the spread between models to be smaller than the gain from a definition. The remaining variable is whether the institution has written down what it means.
Governing definitions: four moves
The institutions closing this gap are not re-running their BCBS 239 programs. They are treating definitions as a governed asset, with the discipline they already apply to models, and they are starting with the numbers they defend most often.
1. Inventory the twenty numbers the institution defends
Begin with the concepts that appear in board packs, regulatory returns, covenant tests and client reports: exposure, customer, default, liquidity, adjusted EBITDA, AUM, and the dozen others specific to the house. For each, record every definition in use, the function and system that produces it, the report it feeds, and the person accountable. This is the inventory MAS now requires and the accountability the FSB's seventh practice asks for, and it is small enough to govern.23,24
- Concrete marker: Every priority concept has a named owner, an enumerated set of variants, and a stated use for each variant, approved by the function that reports it.
- Concrete marker: No variant exists without a reason; variants that cannot be justified are retired, and the retirement is dated.
2. Attach scope, effective date and lineage to every definition
A definition without a date is a dispute waiting for a restatement. Each variant should carry the jurisdiction and portfolio it applies to, the date it took effect, the date it was superseded, and the upstream fields it is computed from. The PRA's finding that reconciliation is often where data problems first surface, and the EBA's and PRA's moves toward harmonized glossaries and data dictionaries, say which way the supervisory side is going.4,5,6 Definitions that are versioned can be reproduced for any reporting date; definitions that are not cannot be audited.
- Concrete marker: Any figure in a board pack or regulatory return can be traced to a definition version, an effective date and an owner without a meeting.
- Concrete marker: Changes to a definition follow a change-control path with a named approver and a recorded reason.
3. Put the governed definitions between the model and the data
The 2026 results are unambiguous that definitions help only when the system is made to use them. A model that can read the schema will write its own definition; a model bound to governed metrics, join paths, grain, filters and access policy cannot. GROUND's progression from 79 percent hallucination to zero, and dbt's finding that a governed layer fails loudly while text-to-SQL fails plausibly, describe the control, not just the catalog.14,15
- Concrete marker: Every AI-generated figure records the definition version, the access policy and the validation checks it passed, so a reviewer or supervisor can reconstruct it.
- Concrete marker: When a question cannot be answered from a governed definition, the system declines and routes it to the owner rather than improvising.
4. Govern the definitions layer under model risk discipline
SR 26-2 already names common assumptions and data as sources of aggregate model risk and makes data selection part of conceptual soundness.7 Applying the same inventory, validation, monitoring and change-control disciplines to definitions turns them into an asset that survives staff turnover, model replacement and the next migration, and answers Machado's fragmented-ownership concern with a structure supervisors already recognize.20
- Concrete marker: The definitions inventory has owners, review cycles, independent validation and a change log, and is reported to the committee that sees the model inventory.
- Concrete marker: Replacing the language model, the warehouse or the vendor does not require rebuilding a single definition.
The leadership test
No institution has finished this work. Leaders can judge where their own stands by asking six questions:
- For our twenty most-defended numbers, how many definitions are in use, and does a system or a person know which one applies to a given report?
- When two functions report different figures for the same concept, is there a recorded owner of the definition, or a meeting?
- Could we reproduce last year's exposure to a counterparty with the definition in force on that date, and prove it?
- If an AI system answered a question about liquidity or default this morning, which definition did it use, and would we learn that from the system or from an interview?
- Which of our definitions carry an access policy, so that the right number is also shown only to the right people?
- If a supervisor's own definitions change next year, as the EBA's and the PRA's are about to, how many of our systems would have to be edited by hand?
Institutions that can answer these questions have governed definitions, whether or not they call them that. Those that cannot have a gap the next model release will widen rather than close, because a more capable model reaches further into the data and applies the first definition it finds faster and more fluently than the last one did. Our flagship paper, The institutional intelligence gap, argued that the layer missing from the AI stack in finance is the institution's own meaning, precedent and decision rights. Definitions are the first and most tractable part of that layer, because every institution already has them, in five versions, waiting to be owned.
The lesson of the BCBS 239 decade is that infrastructure without ownership does not change the number in the board pack. The lesson of the 2026 benchmarks is that the same ownership, expressed as a governed definition with a date and a policy, is worth more to an AI system than any difference between the models now available. The institutions that take both lessons will have one number for exposure, one for default and one for liquidity, each with a name and a date beside it. That sounds modest. In 2026 it is what lets everything else in the AI program be trusted.